Friday, February 21, 2025

GIS Communications - Lab 6 - Bivariate Mapping

 Greetings all!

It is absolutely crazy that this is the last module, minus final, for this class! Where did the time go? This whirlwind experience of a class is culminating with proportional symbols and one of the more unique applications of choropleth styling. That is the multivariate mapping method. In this case I am taking two different variables and visually depicting the trend between them across an area. This final week explored making meaningful proportional symbol legends, establishing an effective color scheme for bivariate choropleth mapping, and creating custom legends by manipulating graphical elements. 

The first map that I will present below is a proportional symbol map which maps the changes in the number of jobs by state. While this is only one variable being mapped, the unique thing is that there are states with positive and states with negative values. So, cumulative gains or losses, being presented. The proportional symbols provide a visual representation of the magnitude of jobs gained or loss. One tricky part of this map is that there are far larger gains than there are losses. So despite the symbol type (circles) being fairly close to one another in size, there are large differences possible on the positive side as compared to the negative side. 


For this map, I went with two separate nested legends. This is predominately because of the (as stated) incredible difference between the high value for positive growth and high value for loss. The Growth section has a much larger proportional symbol range than the loss side. Even though the smallest symbol for growth is portrayed as the same value for the largest symbol for Loss. That is a bit of an illusion when looking at the two comparatively. But in this regard the size difference is key. Additionally, the two symbols are oppositely colored. Blue for positive change, with a green background, and red for a negative change with orange background. 

The second map below focuses on comparing obesity and inactivity statistics at the county level. 


Brewer 2016, Chapter 9 expresses that multivariate mapping excels at showing the relationship and distribution of multiple related variables. In this case, I am applying a sequential – sequential arrangement to convey the interaction between these two related variables. In the previous labs, using the same data set as an example we learned that the dot plot effectively shows that the two variables are correlated. This visual depiction now shows the strength of the relationship and areal distribution of both factors combined. There are significant areas of low inactivity correlated with low obesity (so more active people with less obesity challenge). There are also significant areas of high inactivity percentages combined with high prevalence of obesity.

Unlike the previous labs where we focused on a traditional or single variable choropleth, this bivariate style provides a direct visual comparison of the spatial trends. The 3 x 3 sequential color shades give a strength guide to visualize the interaction between the two. In addition to seeing areas that are highly correlated, we can identify the areas that are particularly one sided or less directly linked, but favoring one over the other variables. Ultimately, the use of this method allows us to better understand the regional dispersion of both variables simultaneously. While this is informative, one accompanying map that I think could provide even more context would be a population distribution choropleth.

While some areas have high or low correlation, we don’t get a sense of how large or small the issue is because we aren’t seeing the total underlying population.  A large population county with a low percentage may still have more people impacted than a low population county with a high percentage problem. Thank you. 


v/r

Brandon

Friday, February 14, 2025

GIS Communication - Lab 5 - Statistics

 Greetings! 

Welcome to Stats week. We continue to work with Choropleth displays as our thematic tool of choice. However, we are adding in some more supporting details. These support statistics and information come in the form of bar graphs, dot plots, and line charts. All of this together is in effort to create an effect data visualization product. 

Before I get to the product below, I do want to discuss one of my primary challenges with this course. The amount of time for finishing. Finishing in this context are those elements of design cohesion and implementation to make an appropriately aesthetic and realized deliverable. While the product below has all of the required items, I think I could definitely enhance it with more time for finishing, or adjusting of some of the color schemes. It's not that I don't think they are effective, I simply think I could refine some more with more time. As a leader in the Air Force I often have to remind people to not let perfect be the enemy of good enough. In this case, with the time that we have, I think it is a good enough product, perhaps the 90% solution, but there is refining work I could do. I would like to introduce some post-processing outside of Arc GIS Pro that can more easily manipulate the graphical elements. 


This final layout uses a converging theme as the largest elements (the maps) on the left step down to a trend analysis on the right. The color themes of the maps and graphs help keep the focus on these items, with the background text supplementing the discussion. One improvement that I would like to have had time for would be to add shadowing or extrusion to the to both United States maps to allow those sections to establish a greater figure / ground relationship. Despite the convergence theme, I also employed an element of symmetry, though there is stair stepping involved. The two bar charts balance each other like the two maps do. Also the two types of data displays, the dot plot and line graph also balance each other with the left showing a downward trend and the right an upper trend. The amplifying text is also symmetrical about the trend line. Further, the background for this portion is a dark brown with white text to differentiate from the mapped portions. I wanted the color to stand out more, but then the text to be easily discernible when focused on. This contrast helps establish better visual balance and a greater hierarchy to the mapped and graphed areas. 

Thanks for stopping by! 


v/r

Brandon


Thursday, February 6, 2025

GIS Communications Lab 4 - Choropleth Maps

 Welcome to Lab 4, discussing one of the most useful and most proliferated (in my opinion) types of thematic maps. The Choropleth map. These are a type of thematic map that use color ramps to provide valuable information about some type of enumeration unit. In the case of the below you will see an example of a couple like color ramps that I created, and one that was pulled from color brewer, a software that helps develop these color ramps for you. Then you will see a map of Colorado, with the counties as the enumeration unit. The counties are colored based on the percentage of population change from 2010 to 2014 in a diverging style based on the equal interval classification method. 

Before we get more into that lets look at some specific color ramps that I created and or worked with. So, to start, there were a set of starting values to choose from. These values are based off of an assigned value between 0 - 255 for Red, Green, and Blue. The combination of these values drives different colors, each of the individual patches in the color ramp has its own unique combination value derived from the RGB combination. 


All three of the color ramps are sequential schemes with various changes in hue, lightness, and saturation. Brewer, 2016 discusses these three things as the basis of understanding perceptual dimensions for color applications. One of the biggest differences between my linear and adjusted progression ramps to the color brewer lamp is the maintaining of the Blue-Green hue. Because the basic color from the lab given directions had slightly more blue added to the green base I kept that offset blend (ranking from most to least, green, blue, red) throughout the ramps. The sequential multi-hue color brewer ramp ends with a much lighter last step, whereas my ramps have a brighter final step. Though the linear progression and adjusted progression are very similar, the 2nd to 3rd and 4th to 5th  of the adjusted progression seem to be closer to one another than their respective steps in the linear progression. One of the biggest things that I learned after this is the adjustment of saturation to reduce the brightness of the lightest value on my two ramps. I can manipulate either the RGB number combination to get a lighter hue, or I can swap to a HSV (Hue, Saturation, Value) combination to more readily adjust singular aspects of the color, like its overall brightness. 

As a reminder, for the map below, I am working with the state of Colorado, with the data applying to the county level. The map is based on highlighting the percentage of population change over 4 years. 


Colorado’s population change is variable between +10% and – 13.5%. Because these highs and lows are relatively symmetric I utilized an Equal Interval approach. Additionally, looking at the histogram, the data only shows a slight positive skewness. Dealing with a somewhat normalized distribution and desire for fairly equal (3-5%) data classes on either side of 0, I decided upon the Equal Interval. One potential downside with equal interval is that it could leave some classes empty when dealing with skewed data. That is not the case here. All classes have multiple observations. I chose 7 classes because I wanted a distinctive 0 class, and each of the positive and negative classes represents approximately 3-5% of change. Now, I did look at using 5 classes, but this created too generic a distribution of class observations. That, and the range increased to approximately 3 – 7% spread. I didn’t think that breakout was as meaningful as the smaller 3-5 rundown. This method allows for a greater understanding of where the most and least change has occurred. 

Population change in this context is not good nor bad, but it is absolutely positive and negative. So I went with the Green – Purple change ramp. I think it was also complimentary to my light blue and dark gray background features. The purple and green are distinctive and have high enough hue / saturation / value to be a positive figure to the other ground features in the visual hierarchy. 

Please let me know if you have any feedback, thank you!

v/r

Brandon

Wednesday, January 29, 2025

GIS Communication; Lab 3 - Terrain Visualization

     Wow, it's already been 3 weeks. How does the time go so fast? Welcome to the discussion on terrain visualization. The two different aspects of this visualization that were the focus of this week are contours and hillshading. The purpose of hillshading is to help convey and understand the 3 dimensional aspects of a region. This is predominately achieved by creating a surface with known elevation, be it a digital elevation model, triangulated irregular network, or digital surface model. A hillshade is also created by applying an illumination source on a scene. Normally this source is simulating the sun from a particular azimuth and elevation. The direction of illumination then casts shadows and illuminates the features or topography based on the direction it originated. There are multiple techniques to apply hillshading, from a traditional singular direction, to multi-directional, which is designed to compile multiple views into one scene. 

The map example below is a culmination of multiple different objectives. I utilized a multidirectional hillshade on a TIN of Yellowstone National Park. Overall, I think the multidirectional technique better highlights ridges and valleys oriented in multiple directions than the traditional unidirectional hillshade. That is the underlying layer in the map below. The colors of the main map are based off of a Land Cover Classification for the park. Multiple types of trees and vegetation are identified by their respective color. Non-forested and water covered areas are also identified. The classified raster was provided with more class break outs than are presented here. For clarity I combined like classes of trees, and then adjusted the colors to reflect the areas things were present. The smallest distinct areas have a brighter color to make them still identifiable, and the lower amount of those regions still keeps them fairly mid ground in the visual hierarchy. This Land Cover layer then gets a level of transparency to let the underlying hillshade show through. This combination gives us a more useful look at the topography and gain more meaning into the distribution of land cover classes. 


I think one thing to be aware of is that the greens may not be the best green for their particular vegetation type. But given that they are still revolving around some evergreens and then some seasonal greens I think it is more appropriate to have the majority of the vegetation in like color. Water is of course water colored, blue, which is useful. So what do you think?

v/r

Brandon


Thursday, January 23, 2025

Communicating GIS, Lab 2 - Coordinates and Projections

 Greetings and hello! 

This week we are looking at the effects of different projection methods and systems on map making. First, for those without a GIS background, what is a projection? A projection is a method for transforming the spherical earth into a flat or two-dimensional map. Different projections have different purposes in that they are designed to maintain some aspect of the earth. These aspects include accurate distances, angles, shapes, or areas. Most projections focus on one or two of these aspects, but when talking about multiple, there are usually smaller distortions in all aspects. 

The overall purpose of this weeks lab was to look at these distortions through different example projections, apply common coordinate systems, and experiment with different projection options. This culminated in creating the Grid & Graticule map below. I utilized Nevada based on where I am currently living. Using it as a study area, I found a Nevada specific projection when encompasses the entirety of the state. 

Interestingly, Nevada has its own projection, called the Nevada State Reference System (NSRS) of 2007. This is a UTM projection and aligns with UTM Zone 12N because the East – West boundary lines of Nevada correspond with that UTM Zone.This is a better choice than the State Plane system because Nevada has 3 State Plane Zones. They are the East, West, and Central zones. For a full state presentation as seen below, UTM Zone 12N is appropriate. There are two datum options that could be utilized however. The NSRS is as of 2007, but there is a UTM 12N with NAD 1983 or 2011 options. I elected to go with the state-specific option for the subsequent map. 


Note the multitude of intersecting lines in this map. What are they? The blue lines represent the Projected Coordinate System and are displayed as a "measured grid." That is a grid that shows measurements on the map based on the values associated with the coordiante system. In this case they are in Meters to go along with the UTM zone. The tan lines on the other hand are for the Geographic Coordinates, and represent a 1 degree interval and are referenced in terms of latitude and longitude. 

While this was a specific application of a projection and grid/graticule, the rest of this lab looked at everything from different whole world presentations to regional specifics. While this hasnt been the first of my GIS classes to look at projections I think this has been the most indepth manipulation and the best overall understanding of how to use them. For that, its an invaluable lab.


v/r

Brandon

Friday, January 17, 2025

GIS Communications, Typography Lab 1

 Greetings! 

Welcome back to the GIS Journey as we kick off our time in GIS 6005 - Communications. Lab 1 focuses on cartography, the basic map elements, and typography. This is an excellent refresher from some of the early GIS courses, and gives renewed focus on the map design principles, and typographic styling. I think that typography is one of the ways to truly define your presentation style. While I dont think I have fully come close to fully defining mine yet, the exercises highlighted below are certainly a step in that direction. Overall, the purpose of the below were to explore techniques for manual and dynamic labeling, and implementing effective design choices. Those design choices need to enable the map to be legible, have visual contrast, deliberate hierarchy, solid figure-ground relationships, and ultimately - balance. 

To that end, the two examples below focus on utilizing a hierarchy to the labeled elements through use of size changes, bolding, italics, font color differences, and positioning. By being able to separate out differences in feature category or feature hierarchy we can help build a more effective map, and this lends to improved visual balance. 

This first example looks at San Francisco and highlights a number of different types of features throughout the city and around it. There are only 16 labeled features on this map, but there is still a deliberate difference in the hierarchy and presentation of the different labels. 


This second example looks at Mexico and balances 3 different types of labels across the whole country. Prominent cities, rivers, and state names are all on display. This is a much more busy map by design, but still, deliberate design choices were applied to each of the label types. From differences in text size, bolding, color and contour differences, the tree types all stand out in different ways. The rivers flow near or along each of their respective rivers. The Cities are tied to representing points, and the states are overall smaller but centered to the max extent able. 


While I think this is still really busy of a scene, I did refine a lot of the goals on placement. With more time I think there could be a good deal of streamlining of the river labels, but for now, it was a great exercise in remember how to manipulate these elements in Arc GIS Pro. 

Thank you! 

v/r

Brandon  


Sunday, October 6, 2024

Special Topics - Mod 3 - Lab 6 - Aggregation and Scale

 Hello and Welcome back! 

My how time has flown. It has almost been 8 weeks, and 6 different labs. There have been so many topics covered in this short time, and here we are hitting on a combination of new and reinforcing of previous once more. 

This final module for Special Topics focuses on how scale and resolution affect vector and raster data respectfully. The overall theme there is on observing some effects with the Modifiable Area Unit Problem (MAUP). That refers to the issue that comes up when reviewing spatial analysis results of a data set across varying scales or changes in size, shape, or boundary of some spatial unit. This leads to the possibility of interpreting the same dataset multiple ways depending on the enumeration unit used. Finally we end that discussion with the ultimate form of boundary manipulation used for political boundaries, gerrymandering. 

A little back to the basics, Scale refers to the overall detail present in a map or scene. Large scale references a higher amount of detail over a smaller geographic area. Conversely small scale is a much broader area with less detain. The larger the scale the more detail we have, the more data and true surface information maintained. 

Resolution for raster data refers to the size of each pixel. The size of the pixel affects the level of detail. Generally put, an object must be larger than the minimum resolution (pixel size) to be distinguishable in a raster image. Again, high resolution has more detail but usually represents a smaller ground area. This does come with the tradeoff of needing much more processing power and digital storage capacity. 

Gerrymandering on the other hand refers to the adjustment of electoral district boundaries to favor a particular party. Its overall goal is to influence election outcomes in that particular district, by having the majority demographic grouped together. There are numerous ways to try to determine the degree to which a district is or isnt gerrymandered. for this module I took two different approaches. I calculated the Polsby-Popper and Reock Compactness scores. They both have a unique formula relating to the area and perimeter length of a congressional district. 

Polsby Popper = 4Ï€ × Area​ / Perimeter2

Reock = Area of District / Area of the Smallest Enclosing Circle

These both focus on comparing the area or perimeter of the district to a similarly sized or enclosed circle. Polsby-Popper looks at a circle of the same perimeter size, and Reock looks at the smallest circle that can hold the district area.

Computationally I was able to do all of the Polsby Popper calculations within a modified Congressional District feature class. The primary modification was to only include the continental United States. The Reock computation involved creating a new feature layer by use of the Minimum Bounding Geometry tool. This tool took all of the data from the District feature and created the smallest circle corresponding to the size of the representative district polygon. From there, the circles area was divided into the district area for comparison. The image below shows some of the "worst offenders" for the Polsby Popper Score. 


This look at the South Eastern United States has 3 different Red areas were were the Top 3 worst scores. 


Here is a zoomed in look at the #3 offender, specifically highlighted because it falls within our very own Florida. You can see that this district covers an area from Orlando to Jacksonville. It also doesnt take a direct path to get there between the two. While the coastal districts are a little more regularly shaped, they are not without impact from Gerrymandering. They too likely have the opposite demographic indicators of this particularly highlighted district. 
Ultimately Gerrymandering is a deliberate manipulation of the political system, but it can be measured and analyzed, thats what the above serves to do, by having applied the same calculation to every district, then excerpting some of the lowest scores. 

It has been a wonderful class, and doesnt feel like this ones concluding. What does that ultimately mean? That even more learning is to come as we jump into the true masters portion of the courseware. Thank you for joining me. 

v/r

Brandon


Sunday, September 29, 2024

Special Topics - Mod2.2 - Lab 5 - Interpolation

 Greetings and welcome to Lab 5!

Interpolation is how we apply values to unknown points based on sample points where we do have known information. These values are predictions based on what we do know. Several different methods of interpolation focus on different statistical or geometric calculations. We will discuss a few of them as they were applied to this week's lab. 

 Thiessen Polygons: these polygons represent an area in which all points contained are measurably closest to the representative data point contained within them. That is, all areas are physically closest to this sample data, not any other sample points. This is a nearest neighbor style analysis.

Inverse Distance Weighting (IDW): this method applies greater weight to nearby points than farther points. This assumes through spatial autocorrelation that a point closer is more alike than those farther. One problem is that it may not capture local variations depending on the effective distribution of the data. 

Spline: This method fits a line through all of the data points present in the set. It seeks to minimize the curvature of the surface, and is good for trying to represent gradual transitions. It can overshoot areas with abrupt changes, but as seen below can present a smoother surface between less harsh phenomena. 

These are only a few of the possible interpolation methods, and are the primary ones discussed in this lab. They were all used to look at a fictitious sample data set for a real place. Specifically, we are looking at points across Tampa Bay to measure Biochemical Oxygen Demand (BOD) in milligrams per liter (Mg/L).

Here is a look at two of the primary methods and how they visually compare: 

IDW:


The thing that I dont think is modeled well by this approach are the Green areas. That is, those areas with a lower concentration.  They are more like localized Low points, when I think they should be more of a balance and transition between the higher areas and lower. That is one thing that is captured better below in my opinion.

Spline: Regularized. 


While also not perfect, I think this presentation does a better job at highlight the transition in zone types. However, it may have missed larger areas that still have a high BOD concentration. 
Regardless, both of these are two different approaches with the same dataset. They seek to estimate the values for areas outside of the measured points. 

This lab further continues to solidify the importance of good sampling methodology. And really we only talked about a few methods, there are so many other choices with varying degrees of difficult calculations included. But as a taste for interpolation it is definitely interesting to see how much the same data set can vary by different presentation models. 

v/r

Brandon

Sunday, September 15, 2024

Special Topics - Mod 2.1 - Lab 4 - Surfaces

 Hello and welcome to the second module for Special Topics! 

In these next two lab weeks we will be looking at Surfaces. This week specifically we are looking at actual ground surfaces through a couple of different tools. Specifically, we are using Triangular Irregular Networks and Digital Elevation Models and comparing similar continuous phenomena with them. In previous classes, we have looked more extensively at DEM's, so for now I will do a little more look at TINs. But first a quick look at what we are working with this week.

There were four different parts of this week's lab which all built on each other. Each part helped build a better understanding of 3d visualized terrain elevation information. It culminated in taking a set of points with elevation (z) information associated. The same set of points was used to create contour lines by first generating a TIN and second generating a DEM. There are a few keys to remember when working with point data like this. 

There are point density considerations, particularly based on the amount of change over the study area. Dr. Morgan simply put, the more points the better (in general). Despite that, more doesn't always matter. It is more appropriate to increase your point density relative to the amount of change in your study area. Flatter areas or those with little terrain variation require fewer sample points to maintain accuracy. More variable terrain or areas with steep changes (mountains, valleys, cliffs, peaks) need a higher point density to retain accuracy. The more sample points in this case let the TIN capture more variations in elevation. Another key point is the idea of critical points. Focusing on critical points like peaks, ridges, and depressions allows a more efficient usage of points than just a consistent distribution of points. 

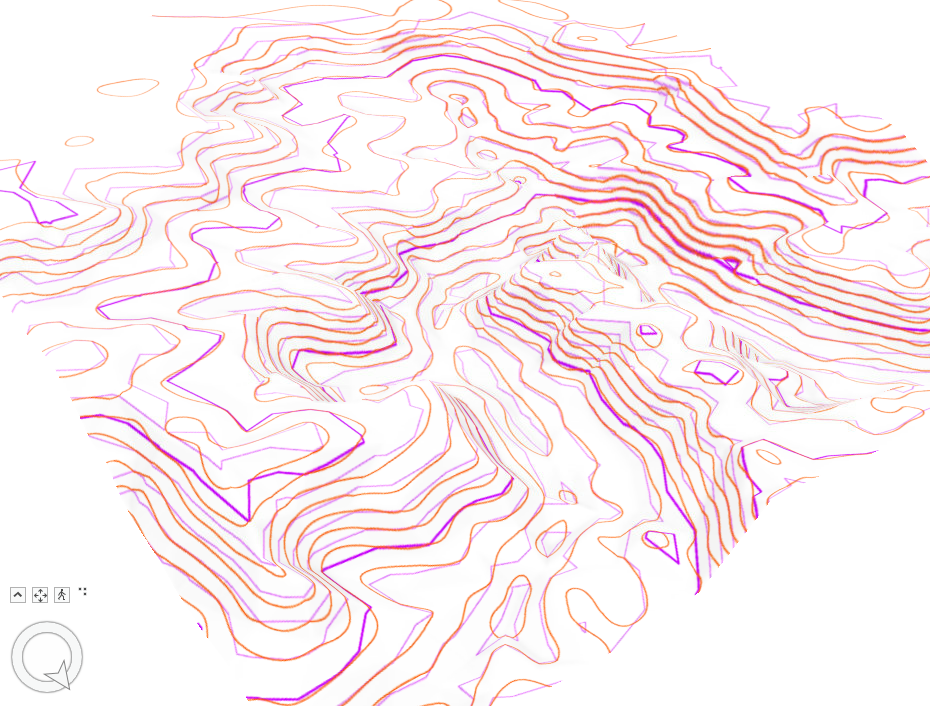
DEM Elevation and Contour Lines: 


TIN Elevation and Contour Lines:


Overlaps in the two derived contour lines: 


Purple / Light Purple: Index Line and Regular Contour for the TIN

Brown/Orange: DEM Contour line

The biggest difference between the two sets of contour lines is that the DEM derived lines are much smoother. The TIN derived lines have much more straight edges and corners for direction shifts. This makes sense, since the TIN is as its name implies, triangular. This gives them a harder, more angular presentation, compared with the smooth rounded DEM contours.  The lines appear to be most similar, or have limited variation in the steeper transitions. But some of the most noticeable shape differences are on the peaks and in the valleys. But there are some instances where it looks like some lines on the TIN jump from one layer to the next, which is not as much the case with the DEM lines. 


v/r

Brandon


Sunday, September 8, 2024

Special Topics - Lab 3 - Network Assessment

 Hello and welcome to Lab 3. This is the culmination of module 1, which explores the interrelated topics of standards, accuracy, precision, and finally a cumulative assessment. This lab evaluates the completeness of two different road networks covering Jackson County, Oregon. 

The two road networks being assessed are from two different sources. The area standard comes from the Jackson County GIS team and will be referenced as the Jackson Centerline feature. The comparison feature is a TIGER 2000 road layer. The assessment of these two features follows Hacklay's (2010) approach discussed in the article "How good is volunteered geographical information? A comparative study of OpenStreetMap and Ordnance Survey datasets" published in Environment and Planning B: Planning and Design 2010, volume 37, pages 682 - 703. 

Following that study there are two basic assessments: first, a simple length comparison of the two features. Completeness in that case is defined as whichever feature has greater length, which came from summarizing the total length of each segment. For the total county, the results were as follows: 

Jackson Centerline: 10,786.5 Km 
TIGER 2000: 11,253 Km

In this case, the TIGER network appears more substantive across Jackson County. 

The second assessment is a little more involved. following Hacklay, a Grid was applied to the County, specifically 297 5x5 Km grid cells. Both road networks were clipped to the grid, and then I determined the total length per cell. This allowed for each cell to be compared for individual completeness and a percentage difference between themselves. Interestingly, when only looking at the grided area, the summary results changed:

Jackson Centerline: 10,671 Km
TIGER 2000: 9,925.7 Km

Following Hacklay's presentation, the cells were determined as follows. 

Cells

Area

Jackson More Detailed (Longer)

163 of 297 cells = 55% or 4,075 SqKm

TIGER More Detailed (Longer)

123 of 297 cells = 41% or 3,075 SqKm

Cells approximately equal

11 of 297 cells = 4% or 275 Sqkm


While the procedures are discussed more in the map, the basic purpose of the grid is to highlight the percentage difference or length difference between the two layers. This was definitely an intensive amount of transformations of the original data and joining the results with the grid. This was a good culmination of all of the previous labs, looking at data accuracy, precision comparisons, and network completeness. Thank you.

v/r

Brandon

Monday, September 2, 2024

Special Topics - Lab 2 - Accuracy Reporting

 Welcome to Lab 2!

This week carries on where last week left off still looking at data accuracy and standards. This week we branch a little deeper into the two types of standards that we could generally be looking for. First, are the National Map Accuracy Standards  (NMAS) of 1947, which were geared more toward printed maps. This standard revolves around allowable positional errors for the maps features, with 90% of well-defined points expected to fall within a map-scale-based tolerance. This standard while still applicable to many printed charts/maps has generally been replaced by the National Standard for Spatial Data Accuracy (NSSDA). This is the current standard which provides a statistical framework for assessing positional accuracy. It uses Root Mean Square Error (RMSE) to quantify how closely the data aligns with actual or true geographic positions. It reports accuracy at a 95% confidence level, which takes either a horizontal or vertical RMSE and applies a statistical multiplier. This approach is more consistent and flexible for digital mapping than the previous standard. 

For this weeks specific project, we looked at two different roads feature classes for Albuquerque, New Mexico. One, provided by the city GIS team, is supposedly the higher resolution standard for the city. The other is a separately provided road network. Both of these were tested against user (my) derived intersection points from 2006 based digital orthographic quarter quad imagery. 


The image above shows the base road network and the sample points which align to intersections throughout the study area. These intersections were then used to compare the reference point, to a point derived from the intersection of the road features polylines, converted to a point. The measured difference in points is used to determine a sum, average, and RMSE. A sampling of the point analysis calculations is below.

The calculations for the full data set result in a set of statistical measures seen below. While the units arent pictured below, remember we are working in feet, based off of the projected coordinate system in use. 


The last thing we do with these calculated results is report it in a semi-standardized method based on the NSSDA. My derived statements for which are below. There is a short statement which could suffice for some reports, or a more in depth detailed statement. I offer both below. 

Horizontal Positional Accuracy (Basic Statement – ABQ Street Data)

Using the National Standard for Spatial Data Accuracy, the City of Albuquerque’s ABQ_Streets data set tested 19.74 feet horizontal accuracy at 95% confidence level.

Horizontal Positional Accuracy (Detailed Statement – ABQ Street Data)

The intersection centerline accuracy of the Albuquerque Street dataset provided by the city of Albuquerque GIS Team was evaluated against a random sampling of intersection center points. The centerline points were observed and derived from 2006 Digital Orthographic Quarter Quad imagery for the study area. This accuracy assessment served to validate the ABQ-Street data as a baseline “high-accuracy” dataset with which to compare other datasets against. The NSSDA accuracy of which was tested at 19.74 feet horizontal accuracy at 95% confidence level.

This was determined through twenty intersections approximating equal spacing throughout the study area. These were adjusted to ensure that the reference sampling points would be applicable to two different street layers, the one discussed here, and a secondary discussed later. Taking the approximate centroid of the selected intersection a new point was derived, and compared against the intersection terminus of the ABQ-Street file, as defined by the intersection vertices transformed to a point feature. The imagery derived reference point and ABQ-Streets derived intersection points were then compared and utilized for the accuracy assessment.

The positional difference in easting and northing was calculated with the results garnering the sum, average, and Root Mean Square Error (RMSE). Following NSSDA guidelines, the RMSE was adjusted to 95% confidence utilizing a multiplier of 1.7308. See the tabular output above. 

Thank you,

Brandon


Tuesday, August 27, 2024

Special Topics - M1 - Data Accuracy

 Hello and welcome to the beginning of Special Topics in GIS. This first module we are looking at data accuracy, quality, and precision. It starts with a look at what these terms mean and moves onto a couple of examples of how to explore accuracy and precision. But before that even we have to establish one key thing; data standards. Bolstad shows us that there are four primary categories of standards: media, formatting, documentation, and our primary focus this week, accuracy standards. 

Accuracy standards document the quality of positional and attribute values or datasets. The lab for this module looked at a few different aspects of this. One, we looked at horizontal precision vs horizontal accuracy, and had a rundown of the possible combinations of these as they apply to a dataset. Accuracy refers to how close a data point is to the true location of what was measured. Precision refers to the consistency or repeatability of results for what was measured. The distance between repeated measurements provides an average deviation. We combine these two terms into a matrix of possible outcomes.

Accurate / Imprecise     Inaccurate / Precise 

Accurate / Precise         Inaccurate / Imprecise

This last combination is of course what we want, data that is repeatably and reliably obtained that is at the desired spot. The map below is an example of a a test whereby a measurement of the same spot was taken with the same piece of equipment 50 times. Then statistical analysis was applied, with a combination of buffer rings to help isolate statistically significant percentages of data, based on standard deviations and normally distributed data. While fairly simplistic, it helps illustrate the point of accuracy and precision while finding the average of all of the measurements. 


That map above only used the measured waypoints and derived the average position. After that initial analysis, excel was used to perform some statistical analysis on a larger dataset. Similar to the above we were looking at measures of accuracy and precision for a dataset with a true point and many measured points, 200 to be exact. 

With this dataset, several things were calculated which are listed below. There is also a cumulative distribution function (CDF) of the results to help visualize the percentile distribution of the dataset.  


Root Mean Square Error (RMSE): 3.06

Minimum: 0.14

Maximum: 6.95

Mean: 2.67

Median: 2.45

68th Percentile: 3.18

90th Percentile: 4.67

95th Percentile: 5.69


Some of these metrics are directly observable in the CDF chart, like the minimum, where the line takes off from zero, and the maximum, where it ends. Also the Percentile measurements correlate to the respective number on the line itself. The RMSE and Mean however are not obtainable just by looking at this graph, but rather require access to the full dataset. 


Overall, this class jumps into the heavy knowledge quickly! But its certainly interesting to see how previous courses have built up to this point. It is certainly fascinating all of the things GIS can be used for, and excel for that matter. Thank you. 

v/r

Brandon

Friday, August 9, 2024

M6 - Post 2 - Corridor Analysis

Welcome back to part 2 of this week's discussion on suitability analysis and least cost pathing. This part picks up with a look at corridor analysis. Where it builds from the previous part is in creating suitability layers, applying them to a weighted overlay, and then building a cost distance model. Based on the following workflow, the below map is of ideal black bear movement areas between two regions of the Coronado National Forest. Based on the bears known habitats, various land cover types, and roadways, each layer was given a suitability factor. Those factors were then weighted, with landcover being primary at 60%, roads and elevations at 20% each. Then a cost-distance corridor was built based on these factors. Those areas are colored by ideal movement areas. Underlying the scene is a hillshade analysis and terrain relief generated from a digital elevation model. 


The red corridor is the ideal movement corridor, and represents only a 1.1 multiplier to the total suitability result. This means that there was an ideal score, then this multiplier applied to it to generate that movement area. The orange is a 1.2 multiplier, and yellow area is a 1.3 multiplier. I think that these are important because when you extend out to the 1.2 and 1.3 multipliers you start to see secondary corridor bands like the smaller orange corridor. While the red is ideal, this still shows that there may be alternative considerations in play. The raw data however shows that the entirety of the region between the two closest portions of the Coronado regions would be viable. The highlighted areas are just Most viable. 

While certainly a lot of work, with multiple levels of iteration in the products, this was a worthwhile investment of time to understand how these tools work, and build off each other. Thank you.


v/r

Brandon 

Wednesday, August 7, 2024

M6 - Post 1 - Suitability Analysis

 This is the first part of a two post final module for GIS 5100, Applications in GIS. 

This last module combines many of the skills that have been acquired, strengthened, and challenged during this course. Specifically, we are working through a significant amount of raster data manipulation to generate a suitability analysis. Under the auspices of being a budding GIS analyst for a property developer, my task was to take five factors, transform data relating to them, and generate a weighted overlay, to provide a suitability assessment for the subject area. 

The subject categories are: Land Cover, Soil Type, Slopes, Streams, and Roads. 

Land Cover was already in raster format, but required reclassification to provide favorable weight to agricultural areas and meadow or grasslands. 

The Soil analysis having previously been completed was a polygon layer requiring conversion to raster, and then adjusting the suitability for arability. 

A DEM was provided so that I could transform it into a Slope raster, and then heavily weight mild slopes. 

For streams, while water is a desirable feature, it was weighted by distance away from it. 

Roadways are key for accessibility and as such heavily weighted based on distance from a roadway out to 1 mile. 

All of these datasets varying factors were given a value of 1 - 5, with 1 being least suitable and 5 being most suitable. This means, that each raster Cell was provided a value on this scale based on the real factor its source raster represented. Then the weighted overlay tool provides a composite score by cell, and based on the weight applied to each factor. 

In the case of the map comparison below, the left pane has all of the five factors being weighted equally. The right pane provides a variable weight as depicted. 


The biggest takeaway is that by weighting the factors differently you can vastly change the amount of suitable or unsuitable area that you are working with. Also remember that the suitability factors created by the Weighted Overlay process must end up in a whole integer. Normal rounding rules apply for each cells value. A cell weighted at 4.29 and 3.75 will both end up being a 4. etc. 

Now stay tuned for part 2 coming up next. 

Saturday, August 3, 2024

M5 - Damage Assessment

This module involved a holistic look at 2012's Hurricane Sandy, from path to shore, and a damage assessment of some of the aftermath. It starts with translating an excel file containing latitude/longitude, strength, wind speed, and time data for the hurricane across its week-long existence. With the course translated from data points to a point feature class, then converted the points to a line. The culmination of that transformation of data is below. 


After the track was established, we switched our focus to the actual damage itself. For this assessment we use a before and after image for the appropriate study area. With the study area identified I digitized points for each of the structures and built out an attribute table combined with predefined information domains. 


Above is a look at the study area in the post-hurricane scene. While it's not a full map with labeling, the Red and Black triangles indicate total destruction, red highlights major damage, orange, minor structural damage, and yellow represents affected structure. Nearly everything here is affected in some way, but several structures appear intact from this view, those are the green circles.   

From there, part of the analysis turned to looking at damage rates in 100-meter zones. This allows us to extrapolate damage predictions for other areas. Now there are several variabilities, and any given adjacent area may have more or less destruction for a multitude of factors. 


In the above, the line in the center of the buffer is the baseline. Its adjacent to the study area, and shows a visual depiction of 100m bands the study area houses fall in. 

One of the other aspects of the module was to explore external GIS tools, like survey123.arcgis.com which allows for custom survey creation that responders or local citizens can use to submit information. UWF Members can view an example here: https://arcg.is/1CeafO

This comprehensive analysis was definitely time consuming. But it is amazing to see all of the data come together in this way. Thank you.


v/r

Brandon


Saturday, July 27, 2024

M4 - Flood Analysis

 This week involves coastal flood analysis. Both of the below maps look at damage from severe storms or storm surge. The first of which looks directly at pre and post Hurricane Sandy elevation data from 2012 in New Jersey. That analysis utilizes change detection to show where damage areas are, where debris accumulation or shoreline accretion is taking place. The second map is of Naples Florida and is solely based on if there was a 1 meter storm surge what properties would be impacted. The crux is that two different elevation models are being compared to take the analysis a step further. All of this is helping to better understand coastal flood assessments, and how elevation models can be used to delineate coastal flood zones. Numerous raster analysis and modifications were undertaken to process the various LiDAR and DEM data. Followed by attribute table manipulation to determine some accuracy statistics between the two mentioned elevation models which will be discussed more below. 


The map above is essentially a hot and cold heat map, where hot is areas of high negative change. This means for example, a location where a building previously stood which is now gone. The opposite of this is the blue areas which indicate a positive change in that location. This for example could indicate areas where debris has accumulated, or sand has piled up. The information on the map also discusses some of how it came to be, but in simple terms it is the combining of a before raster with a post raster, specifically isolating the elevation change.

Now onto the storm surge map. 


The map above looks at a comparison of USGS DEM derived from traditional photogrammetry against one using a higher-resolution LiDAR dataset. Each dataset was transformed to only show areas where it predicts a 1 meter surge impact. The LiDAR layer is over the USGS layer, but both have areas where the other is not a factor. Because of the scale of the Naples and Marcos Island scene I wanted to provide a better look at how the two data layers are overlapping or not, so I provided an equally sized inset of Naples. There you can see representative examples of each of the impact types. From those buildings not impacted, to those only represented on one DEM dataset, to those represented on both datasets. In this case the most true representation of buildings impacted would be those that are Red for "both" and those that are blue, for LiDAR only. The red and blue together would be the most likely to be impacted. The orange USGS only, would likely not be impacted as its dataset was more coarse when analyzed. 

These are some excellent tools to determine flooded areas from elevation data, and impacted facilities. Thank you. 


v/r

Brandon 

Friday, July 19, 2024

M3 - Visibility Analysis and ArcGIS Online

    This week took us to ESRI direct, utilizing ArcGIS Online and 4 different ESRI hosted training sessions. The theme? Visibility analysis. This week carries forward with our look at LiDAR last week, by continuing to use some similar products, working with elevation layers and overlapping features of varying heights, shapes, sizes, make up types (points, lines, polygons) to work with different portrayals of 3D information. The modules themselves were:  

  • Introduction to 3D Visualization 
  • Performing Line of Sight Analysis 
  • Performing Viewshed Analysis in ArcGIS Pro
  • Sharing 3D Content Using Scene Layer Packages 

    These modules all served to highlight how helpful 3D data and information presentation or visuals can be in identifying patterns not seen in 2D. They aid in providing new perspective of vertical content, and provides an extra sense of realism with the ability to navigate and explore in a 3D manipulable environment. 

    One of the key takeaways was in understanding the difference between a local scene and a global seen. They both typically revolve around the scale of information you are working with, but more explicitly in how they convey real-world perspective vs real-world context. One key difference being if the curvature of the earth is a factor in your information presentation or not. 

    We continued to work with LAS data, DEM's or other forms of elevation layers, but also with Z-values which provide the third dimension for points, lines, and polygons. 

    For points, you could add a height extrusion, such as showing how tall trees are, or lamp posts. For lines, you could establish a standard height above ground for a fence line, or make a particularly uniform elevation boundary. Polygons with Z information gain new dimensions as the shapes are shown. From a square or circle in the 2D to a full 3D building structure. 

    Other analyses can then be done with a fully extruded 3D scene. Line of sight and viewshed analysis was a big part of this weeks training. These revolved around constructing sight lines, then building lines of sight. Whats the difference you ask? Constructing sight lines involves an observation point with known elevation and a target point with known elevation and generating a line between the two. Then, the line of sight utility is used to determine if there are any obstacles from the observer to the target. Buildings, terrain changes, trees or foliage features, etc can all block line of sight. A viewshed takes this a step further in being able to establish what is in view based on what elevation and field of view parameters.


    To take it a step further and apply it to the real world, look at the news this week, there are all sorts of graphics being modeled and analyzed after former President Trump was shot at. Building models, sight line distances, camera vantage points, obstruction analysis. All going on in the real world this week is the exact substance of this module. 

    Regardless of the ongoing real world applications, this module was culminated in creating a shareable scene layer package. An example of the type of deliverable generated for this is below. 


    Overall, these are all hugely relevant skills for GIS applications. They allow you to explore your data more in depth and provide much more immersive presentations. Onto the next week. 


V/r


Brandon


Sunday, July 14, 2024

M2 - Biomass Density Analysis

This is the first of two weeks working with Light Detection and Ranging (LiDAR). This week we are working with data acquired from the Virginia Geographic Information Network (VGIN). A LiDAR point cloud was acquired for one of the park and valley areas in the Shenandoah National Park.

With the singular point cloud several different products and transformations were made to derive the biomass density map below. The point cloud itself (seen in the second image) is a 3d feature layer as height is involved with each point in the cloud. The primary transformation involved deriving ground and elevation data to generate a Digital Elevation Model (DEM), and a Digital Surface Model (DSM).

Interestingly, there is quite a sequence of tool use to generate these deliverables.
- LAS to Multipoint > Point to Raster > Is Null > Con > Plus > Float > Divide

Note that this sequence is either transforming the data type, as in the LAS to point or point to raster. Or it is an adjustment to the cell values in the case of the remainder of the string. The Divide tool is different as it is a combination of the ground and surface data which provides for our final output below. 


The biomass density map above shows the cumulative height by pixel for the entire scene. The DSM and DEM scenes have been averaged together to give each cell a 0 – 1 value. This allows the higher values to show denser vegetation and the lower values to show less height or less dense areas. This is helpful to forresters because it can indicate areas of highest / densest brush. From the image here you can see that these areas follow the contours of the valley in the north / north east portion of the scene. The scene can also highlight the difference between lower scrub compared to the high trees, areas where plains may be compared to tree thickets. 


As described in the map above you can see the LiDAR point cloud which was then used to transform into the raster based DEM on the left. While all of the images above are the exact same area, they are transformations or translations of this point cloud. 

This was an interesting lab with significant tool usage, but it is overall interesting to see how it can be transformed from raw data to a useable product. Thank you.


v/r

Brandon

Thursday, July 4, 2024

M1 - Crime Analysis

    Have you ever wanted to be a Crime Stopper? While you might not reach that milestone with this module, but you can certainly become a better crime analyzer! Analyzing crime through spatial correlation and heat mapping is the name of the game in this module. 

    The overall goals of the module involved gaining familiarity with GIS analysis tools and processes that can help in crime analysis. These allow us to convey and illustrate crime rates, and help derive spatial patterns based on socio-economic characteristics. The same data set was used in three different processes to derive the outputs below. 

    Specifically, a grid cell analysis, kernel density analysis, and Anselin Local Moran's I analysis were all performed with 2017 homicide data for the greater Chicago area. The below are not fully finished maps that would otherwise incorporate our traditional map elements. This would include an actual title, legend, scalebar,  north arrow, and other potentially enhancing information. They are designed to showcase the same data in three different ways. They all highlight spatial clustering for the homicide data, or where the data suggest the highest rates or prevalence occurred in the subject year. A brief rundown of each is below.

Grid Cell Method:

    Happily, the ½ mile by ½ mile grid feature was provided for the study area. This grid was spatially joined with the homicide point feature for 2017. From there, only grids that actually had a homicide occurrence were desired, so they were selected by attribute.

    Of those cells with homicides, this study called for focusing on the top 20%, which resulted in 62 individual cells. That exported feature class was then dissolved to a singular feature. This was for visual presentation, not statistical relevance. 


Kernel Density Method:

    The Kernel Density tool takes a point feature class and transforms it to a raster output using a “magnitude-per-unit area calculation. For this specific tool, I utilized an output cell size of 100 sq feet, and a search radius of 2,630 sq ft or approximately ½ mile, the output of which generates density based image.

    From there, the mean value (2.76) is established, and to highlight the most dense areas I used three times the mean (6.71). These then, were the most homicide prone regions of Chicago for that year, 2017. From there, the image was reclassified using this breakdown into 2 classes, below 3 times the mean, and above. That output was then transformed via the raster to polygon tool. Because the output had 2 values, we only wanted the one that represented above three times the mean. A select by attributes process was used to gain only those areas above three times the mean, and exported as a standalone feature for display. 


Local Moran’s I:

    This process utilizes a normalization of the census tract housing data combined with the homicide data. As in previous processes, a spatial join was performed with the homicide feature and the census tracts. From there, a new data field was created to calculate the number of homicides per 1000 households.

    The Anselin Local Moran’s I tool, was then used to identify statistically significant clustering and outliers. Specifically, we want to identify areas with a high homicide rate in close proximity to other areas with a high homicide rate (HH areas). As opposed to other combinations that are high / low, low / low, low / high, respectively. Once the High/High areas were identified, they were selected using a SQL query, and exported to their own feature class. This class is then likewise dissolved into a single feature. 


    Overall, the provided instructions ensured that there weren't too many issues during the processing of this module. some of the most time consuming parts were in comparing the tables and validating the fields for the various joins that were used. Then selecting the correct inputs for the various SQL queries and attribute selection actions. It is quite interesting how the same data can be aggregated and presented in multiple different ways to draw different conclusions. Thank you.


v/r

Brandon


GIS Communications - Lab 6 - Bivariate Mapping

 Greetings all! It is absolutely crazy that this is the last module, minus final, for this class! Where did the time go? This whirlwind expe...